Looking for the questions that decide.
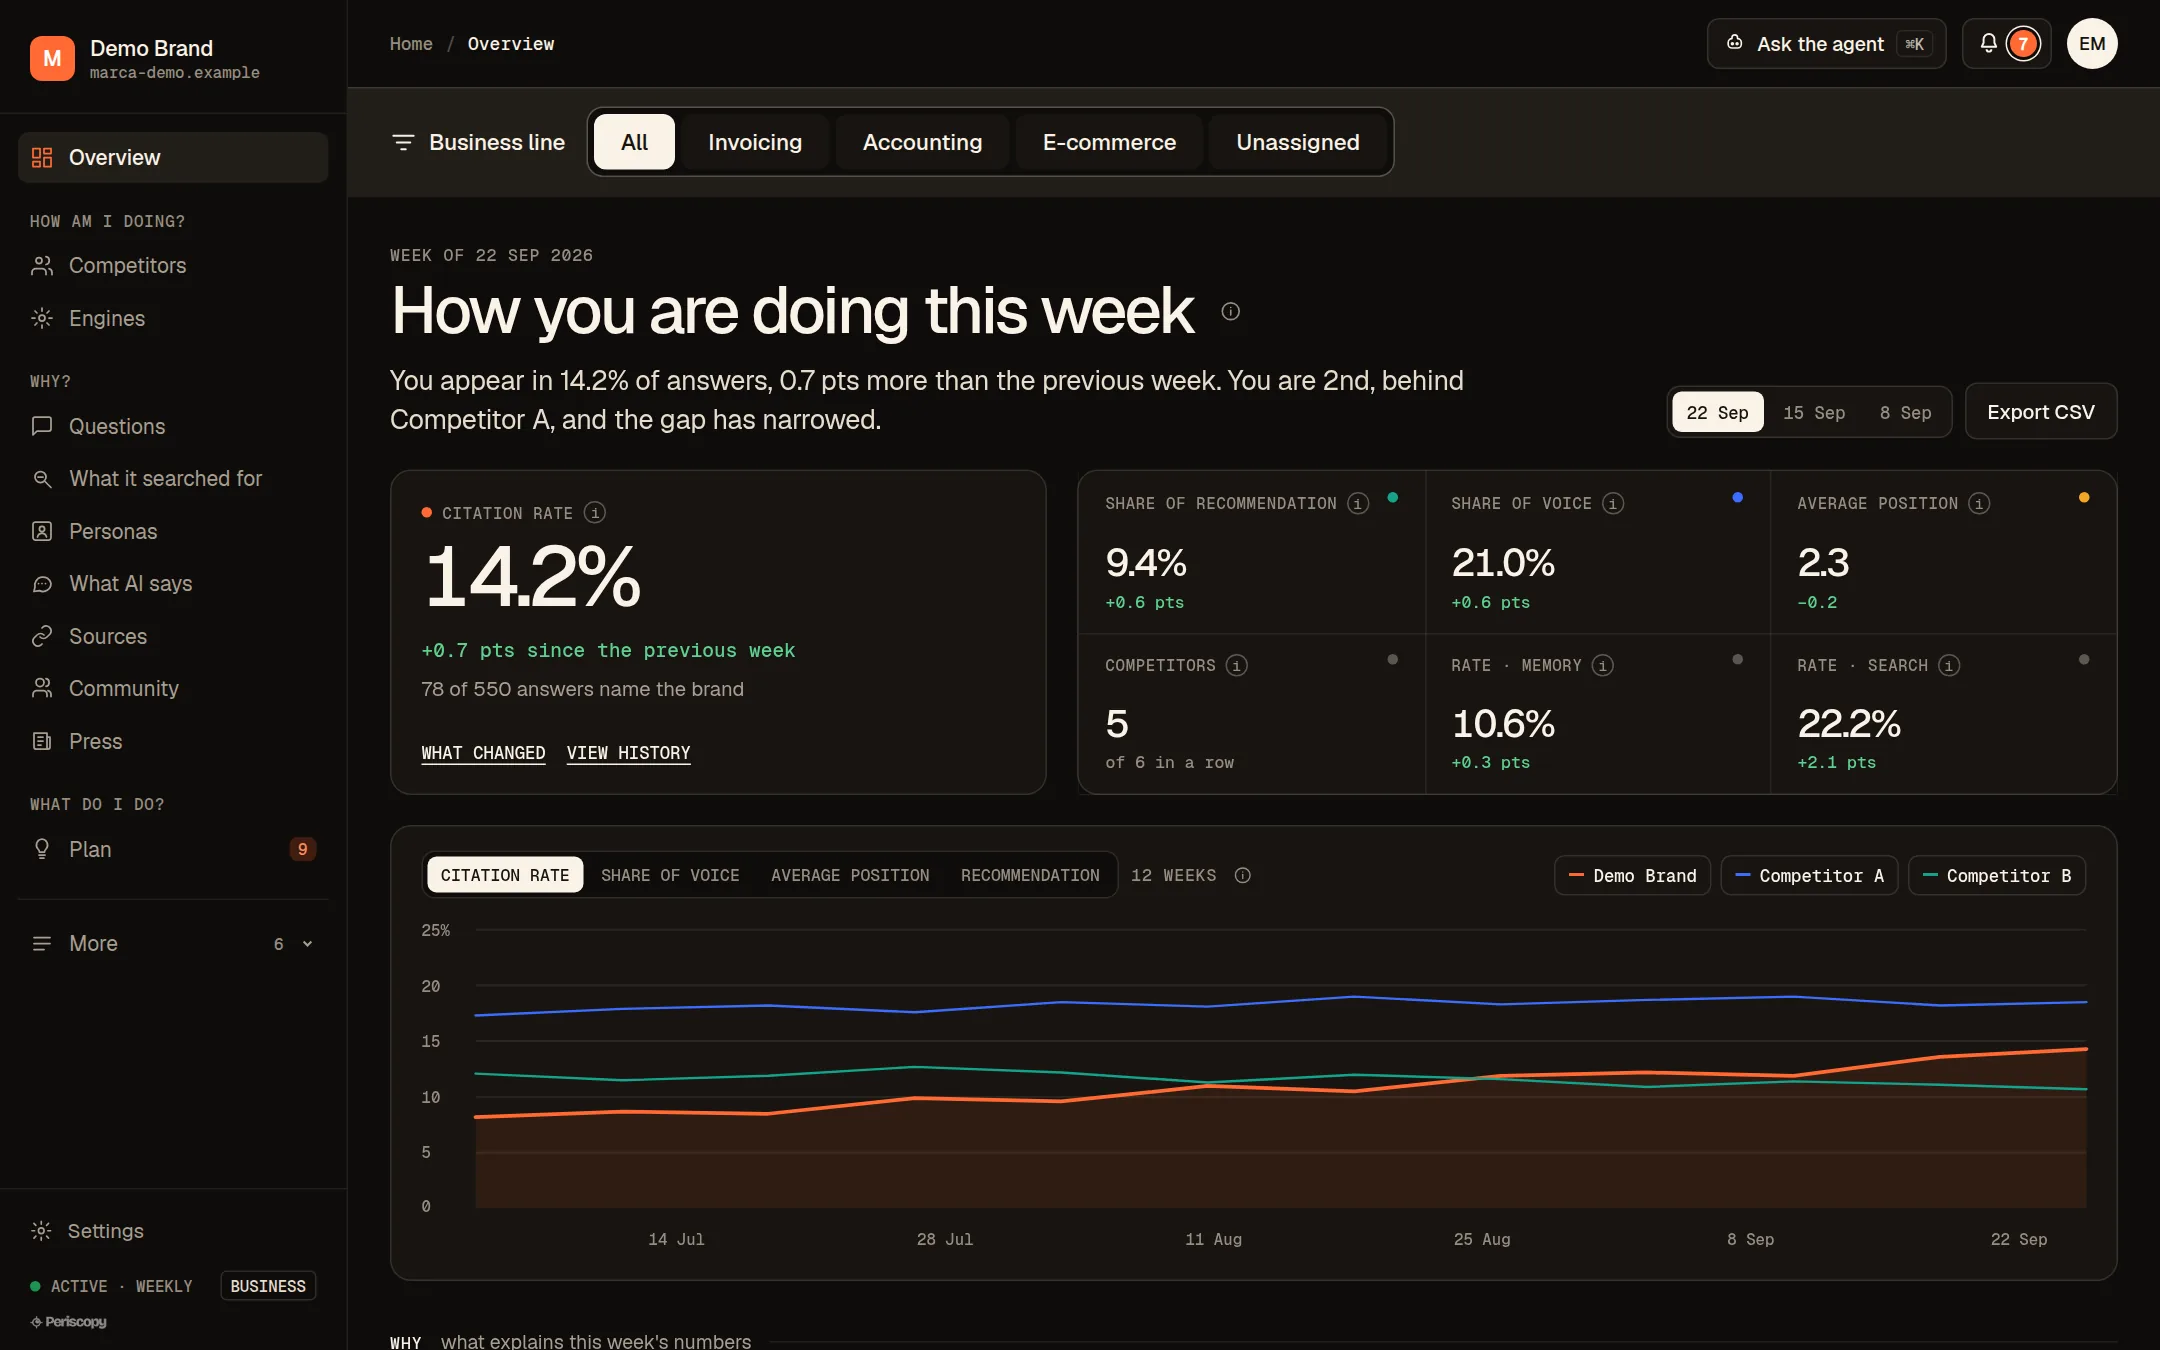
Every dot is a question a buyer asks AI. We run them all, across eleven engines, and show the ones that lead to you and the ones that lead to a competitor. Hover over it.
How we choose the questionsIt is not a dashboard. It is an agent working for your brand.
Every week, without anyone asking: it measures, reads, explains, decides what matters and prepares the pieces. Ten systems cross-read into one reading.
What AI states, against the facts.
Prices, addresses and terms checked against the record. Every mismatch becomes a fix before a buyer reads it.
Measured the way the buyer asks.
Every question carries the framing of a persona and a funnel stage: the decision-maker, the technical lead, the local buyer.
The sites AI reads, question by question.
Which domains each engine cites when it searches, question by question, and which ones repeat across engines. That is where your content needs to be.
Appearing is not being recommended.
We separate a brand named in a list from the brand the answer picks. That is share of recommendation, next to share of voice.
Shopping carousels, seen from the inside.
Title, merchant, price, rating, position and sponsored badge, item by item, as the buyer sees them.
When the brand drops out, you know the same week.
A fall in citation, share of voice or position against the week before, and the week it stopped being named, engine by engine.
One system. Not a list of loose services.
Everything we measure feeds a single brain, the SINAL method, and everything it decides becomes a product you use and an action we carry out. Top to bottom, no black box.
 ChatGPT
 Claude
 Gemini
 Grok
 DeepSeek
 Mistral
 Perplexity
 AI Overviews (Google)AI Mode (Google)
 Copilot (Microsoft)
 Meta AI
For the brands that cannot be left out of the answer. And for the agencies that serve them.
The full service, with Periscopy included.
We measure, decide and execute: schema, citable content, entity, PR in the sources the models read. For digital brands and brands with an address, across several business lines and markets.
The measurement is ours. The tool in front is yours.
An agency account with as many clients as you want. Periscopy with your logo, your colours and your domain. Whoever logs in to see the numbers sees the agency.
A closed loop. No black box.
Measure
Hundreds of real buyer questions, by persona and funnel stage, across eleven engines.
Decide
Every measured gap becomes a prioritised action, with severity and effort, over 4 horizons.
Execute
Schema, llms.txt, citable content, entity and PR in the sources the models read. We implement it.
Prove
Every action gets a date. The next measurement says whether the answer moved, engine by engine.
Seven questions for any GEO provider.
Ask them of us too. Every answer of ours has public proof.
“Common practice” describes the market pattern, not any specific vendor. There are exceptions. And if you find one that fills the whole column, compare us line by line.
of mentions become a choice when you ask for the best Portuguese brands. Being named is not being chosen.
16 questions about the best company in each sector, 10 AI assistants, 616 answers read one by one. In supermarkets, 96% of mentions are choices. In banking, rewording the question reorders the ranking. Open data, published method.
See also the Portuguese B2B SaaS study (45 companies: 56% recommended by no assistant), the Google against AI barometer (251 B2B companies: 41% invisible in AI despite strength on Google) and the measured cases.
We do not promise visibility. We measure it.
It is no longer just the text AI writes. It is the products it shows with prices and stars, the Amazon assistant that picks for you, the press, reviews and forums all of it comes from. We measure that whole layer with our own software, every week, and we do the work that changes the answer.
We run your buyers' questions where they actually ask them: assistants, the products AI shows with prices, maps and reviews. You don't get a report. You get the fixes shipped, measured week over week, and the models that anticipate the next answer.
- Product
Periscopy measures eleven engines and surfaces every week, from inside your market, and turns every measured gap into a fix that gets implemented. See the product →
- Method
SINAL: eight dimensions, from the technical foundation to positioning, documented and published. No black box. Read the playbook →
- Data and models
Every week of measurement extends a database of our own: series of answers, sources, interventions. On top of it we build market models and studies with primary data. See the studies →
What we do and how we work → · Who we are and who we work for → · Products, prices and ads in AI →
What people ask before the call.
GEO (Generative Engine Optimization) is the set of technical and editorial practices that make a brand citable by generative AI models: structured schema, extractable content, external authority and infrastructure such as llms.txt. It complements classic SEO.
The live-search route moves in weeks. The training-memory route moves in months, because it depends on sources that third parties publish and models absorb. Anyone promising ChatGPT presence in thirty days is improvising.
Classical SEO is the substrate and still produces most of the lift. It is not sufficient: a model can rank you well in search and never mention you in an answer, because the answer is assembled from what it knows and what it retrieves, not from a ranked list.
Yes. Periscopy comes in white label, with an agency account and a client portfolio. The agency chooses measurement only or execution as well.
Every project has a different context: volume of questions, markets, business lines. We give a fixed number in a 30-minute call.
Be one of the three.
We run hundreds of real buyer questions and tell you who shows up in your place, and why. No cost, no commitment.